
They say “a picture is worth 1000 words.” If that’s true then a 30sec video at 30 frames per sec is worth roughly 1000 pictures or 1MM words.
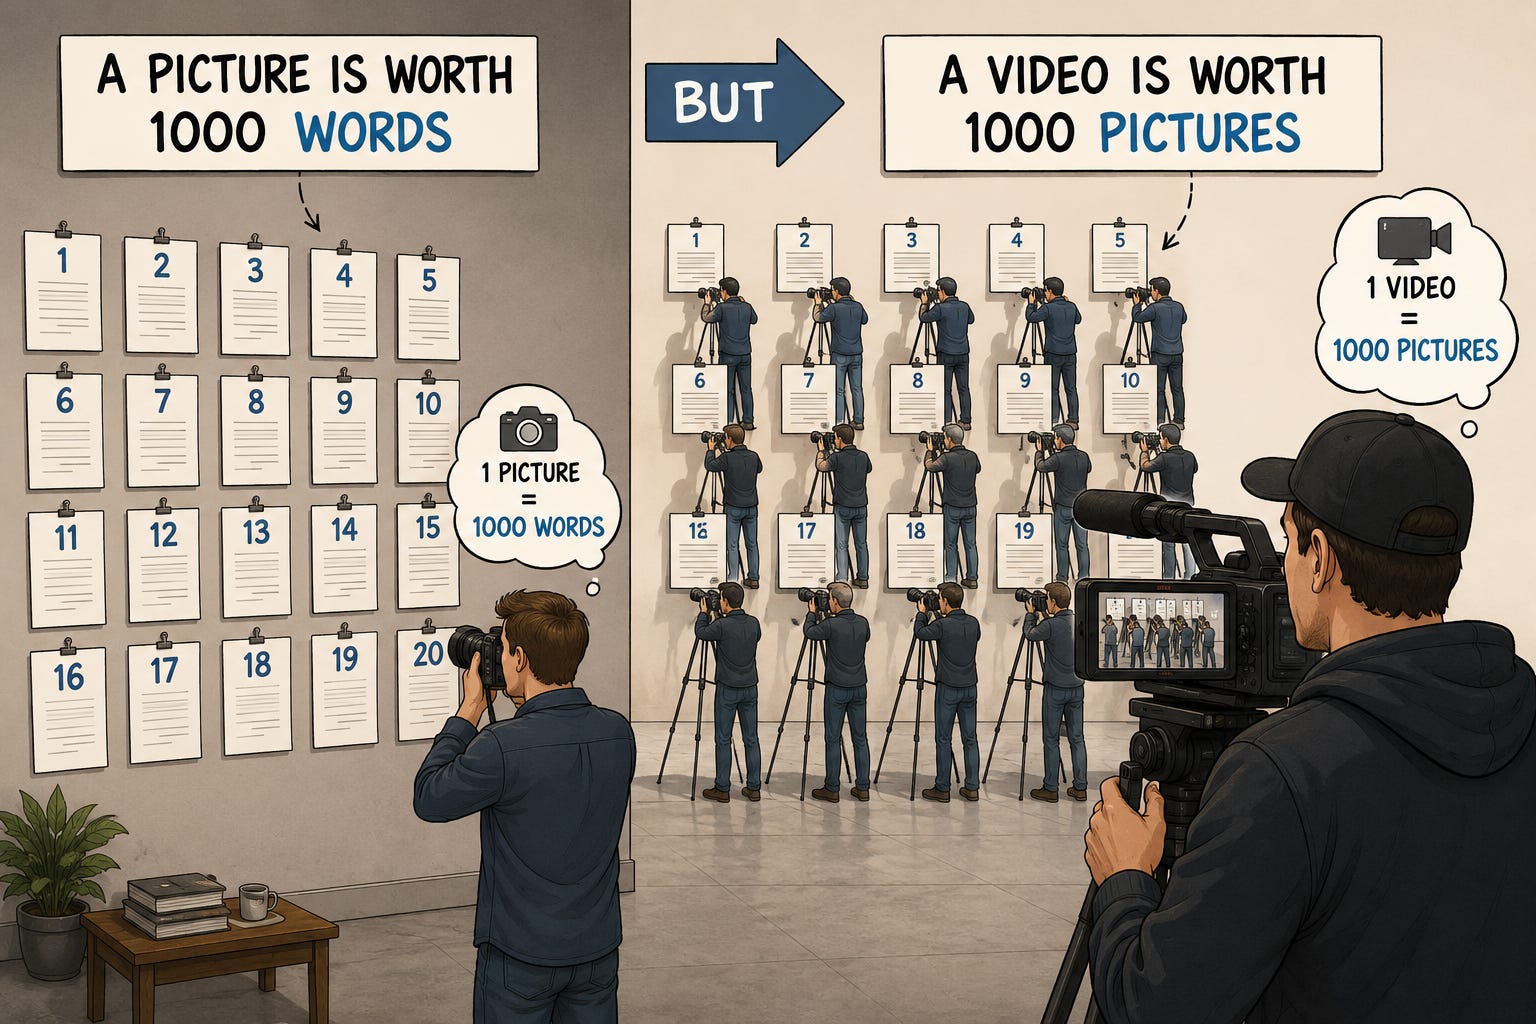
If your job involves Agentic AI then you likely spend a good portion of your time conveying complex, nuanced directions to your agent daily by pasting annotated screenshots and writing paragraphs of narrative text to explain current and desired behavior. I was doing this for a long time until I had the “1MM words” epiphany.
My workflow for the past few months has been to freehand write out my priority list on my reMarkable tablet in the morning of all my high-level todo’s prioritized by importance. I then record a followup Loom video in which I narrate my list cross-referencing the notes from the reMarkable app on my iPad with web pages and anything necessary for explaining the rationale and goal of each request.
Claude Code is my daily driver and already has read/write access to my tablet to be able to ingest and transcribe my handwritten notes so when I’m doing the loom vid narrating my list, it has already scanned it and I’m just enriching what it has with context and explanation. This has yielded a complete step change in terms of my ability to convey high-level goals accurately with near flawless information fidelity at high speed. I then have CC parrot back its understanding of my directives before it launches into anything and 98% of the time it gets the list exactly right, deconstructs goals into its own actionable todo’s, asks any clarifying questions and then just goes and executes. And because it has my narrated rationale and stream-of-consciousness thoughts it on occasion can catch false assumptions on my part and provide even better suggestions than I had proposed.
How it works
Here’s an example of the most recent Loom I just recorded:
iOS recording - 18 Jul 2026 - Watch Video
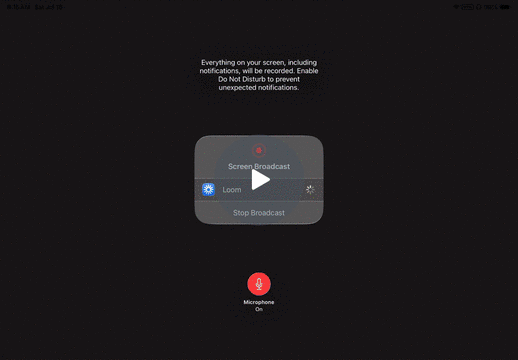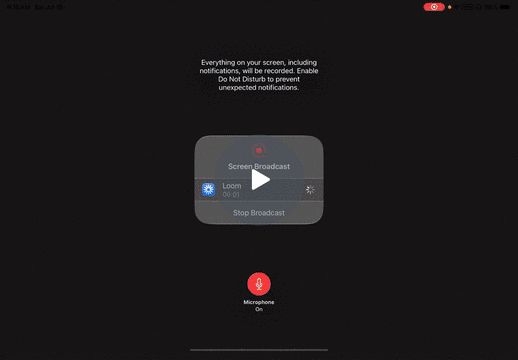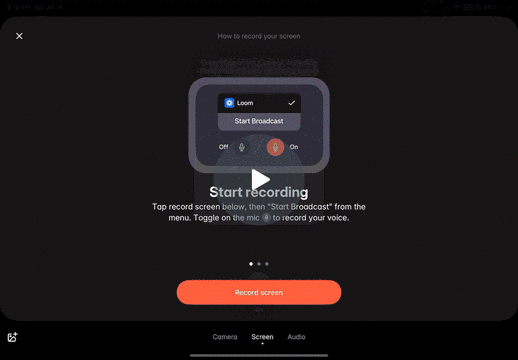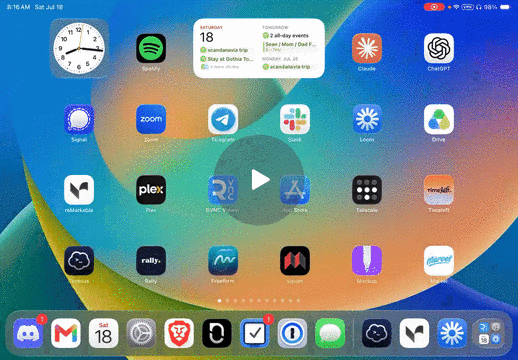
What’s actually happening behind the scenes via the video ingestion skill is CC:
Downloads and parses the transcript
Downloads the video file and uses ffmpeg to parse it into frames
It then correlates by timestamp in the transcript which frames correspond to my narration so it can understand when I say “Move this here” exactly what I’m pointing to and talking about.
I use this not only for software engineering tasks in reproducing bugs or conveying ideas for complex UX sequences that involve many screens, conditionals and lots of moving parts but as you can see in my example video, I am using it for handling high-level operational issues across many aspects of my life now. I have it integrated to SiYuan as my second brain and it uses that system as persistent long-term context storage with Memory MCP as short-term context storage. Combined with various tools/skills it enables it to serve essentially as my EA automating a ton of admin for me.
How to set it up
I’ve made this skill available via ClawHub.ai here so you can get it with a single line install:
clawhub install @scrollinondubs/loom-visionOr if you prefer you can grab the source code directly from github here. It comes as a core primitive of Behalf.bot along with the ability to read/write OTA to the reMarkable tablet. Installation is straightforward via the README and it should work with both Claude Code and Claude Cowork as well as any LLM powering OpenClaw.
Nota bene: I teach my systems thinking-based approach to using CC via this course and as well run weekly office hours helping people gain leverage with Agentic AI in their lives via Vibecode Lisboa. I’m also in process of recording a follow-on second half to that course that teaches how I use Behalf.bot as my EA for high-leverage operation as a solopreneur - if you want to be the first to receive that course, request a notification here. Hopefully this skill helps you streamline how you’re interacting with your agent and improves your efficiency.